
Nvidia and Cisco announced plans for Ultra-Dense Small Form Factor Pluggable (USFP), a new high-density 400Gb/s-per-lane optical module designed to equip the hardware ecosystem for the next generation of AI factories using pluggable transceivers.
As AI models grow and inference demand expands, AI factories must connect more computing systems while managing network complexity, power and costs. Moving more data per watt and per switch helps operators make better use of their infrastructure investments, Nvidia said.
Scaling AI factories requires more bandwidth per connection and more connections per switch. When a switch reaches its capacity, further network expansion can require additional switch layers and optical links, increasing latency, power consumption and costs.
In a press briefing, Joe DeLaere, senior manager of AI factory solutions at Nvidia said Nvidia is opening up the Vera Rubin architecture and will contribute to the open standards that will allow the industry to scale AI factories worldwide.
He said the Nvidia full stack AI factory platform is vertically integrated, but horizontally open.
“We contribute to the ecosystem at every layer of this platform. So at the top, we have more than 500 open models and 250 open datasets that we have contributed to the ecosystem. We also work with the ecosystem on compute software and frameworks.”
He said the company’s contributions today for the project “come from many generations of product experience across the entire stack, and overall, these contributions help the ecosystem accelerate AI factory buildout and increase AI productivity. So it benefits the entire industry.”
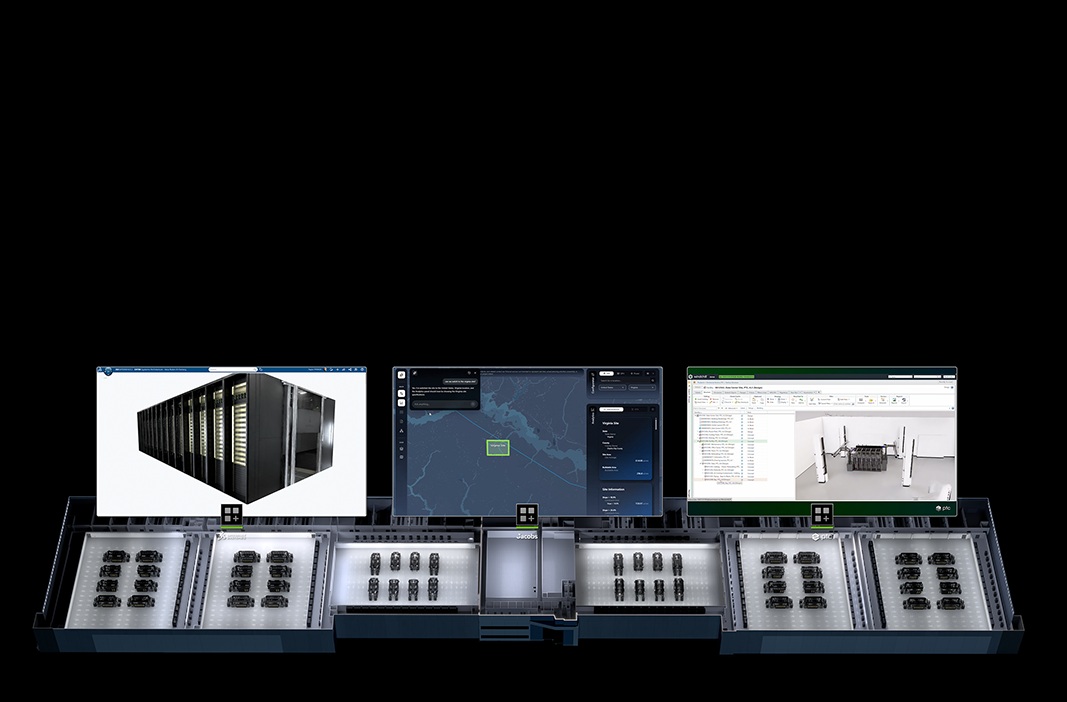
Nvidia is contributing the Vera Rubin platform rack and tray designs to OCP, he said. This includes significant updates over the prior generation, including power, cooling, mechanicals across dozens of different aspects.
The three key innovations in the tray include the compute tray has no cables, no hoses, orfans. Everything’s liquid cooled and modular, and that turns hours into minutes for the tray assembly, he said, speeding up the serviceability and also the overall rack build times.
Nvidia can now carry 5,000 amps on the liquid-cooled busbar without making the rack bigger.
“So this gives us more compute density, more power density in the same space,” he said.
The innovations mean that Vera can come to the market in multiple form factors servers using the same architecture and design principles. And for real agent tasks running on real code in real containers, Vera Rubin is seeing 1.8 times higher performance. Meta has measured two times more performance for hyperscale cloud.
USFP is designed to enable AI factory builders to scale from 200 Gb/s per lane to 400Gb/s-per-lane Ethernet AI fabrics, while extending a deployment model proven at scale across multiple generations of data center networks. With USFP, customers can embrace next-generation optical technology and meet the performance demand of AI workloads without overhauling their data center infrastructure.
The first planned USFP-based transceivers will pack 16 full-duplex lanes in an octal small form factor (OSFP)-sized footprint supporting both switches and SuperNICs, with the ability to expand to 32 and more lanes in the future. By doubling both the lane count and bandwidth per lane, USFP enables AI fabrics to connect more 1.6Tb/s endpoints without adding network tiers. Customers will be able to achieve 12.8Tb/s of overall capacity with USFP.
Comparable with an OSFP-sized module, it delivers four times the bandwidth and frontpanel bandwidth density, with approximately 1.3 times the power efficiency, versus 200Gb/s-per-lane pluggable modules. This means AI builders can increase their compute scale within the same network footprint, while decreasing networking’s share of the overall AI factory power budget.
“Building the world’s largest AI factories starts with rethinking the smallest of connections,” said Gilad Shainer, senior vice president Nvidia, in a statement. “With USFP, Nvidia and Cisco are building an ecosystem to reinvent pluggable optics — connecting more computing with greater efficiency to power the next generation of AI factories.”
“AI builders need an interconnect architecture that can scale performance without locking them into a more complex operating model,” said Bill Gartner, senior vice president and general manager of optical systems and optics at Cisco, in a statement. “Cisco and Nvidia recognized that scaling pluggable optics to 400Gb/s per lane would require more than another incremental extension of today’s module designs. Through our collaboration, USFP is designed to deliver a new level of bandwidth density while preserving the serviceability, deployment flexibility and operational simplicity of pluggable optics. By taking a full-stack approach — from silicon and systems to optics and the network operating system — we can optimize every layer to deliver the performance and scale the next generation of AI networks will require.”
More AI Infrastructure From Every Switch
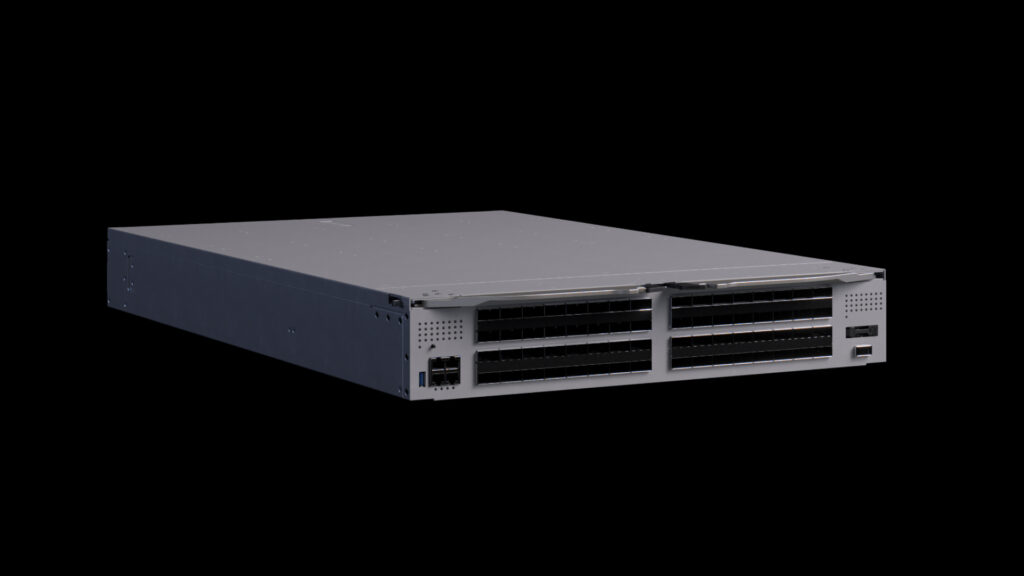
Designed for electrical signals of 400Gb/s per lane, USFP uses a new twodimensional array connector with a two-step insertion design that engages highspeed contacts after the module is inserted, reducing contact wear, improving signal integrity and making insertion force more predictable. The connector technology allows for further scaling of lane count to 32 full duplex lanes and more in the future. Because the connector is designed for 400Gb/s performance, it also offers improved performance at 200Gb/s per lane.
USFP supports power dissipation of up to 100 watts without needing a separate, dedicated embedded cooling circuit within the transceiver, reducing switch design complexity and improving reliability. Together, these capabilities enable higherbandwidth fabrics while preserving the mature deployment, serviceability and manufacturability of existing pluggable transceivers.
All USFP configurations support optical designs that reduce latency and power consumption by simplifying signal processing. Support for a broad range of optical technologies and connection distances gives system designers the flexibility to meet unique AI factory deployment needs.
A Hardware Ecosystem for Next-Generation AI Factories
Nvidia and Cisco are collaborating with TE Connectivity and Amphenol to build USFP cages, connectors and modules, with additional partners expected to join. The shared form factor gives suppliers a common foundation for developing highdensity pluggable infrastructure for 400Gb/s-per-lane fabrics to build a robust ecosystem for AI factory builders.
The collaboration builds on Nvidia and Cisco’s existing work to ensure Nvidia Spectrum-X Ethernet networking and Cisco Silicon One-based Ethernet networks work together seamlessly, simplifying AI infrastructure deployment for enterprises, neoclouds and sovereign clouds.
Nvidia and Cisco plan to create an open industry specification for USFP through an upcoming community-led multi-source project.